
Nvidia Nemotron Lightning Review: Pros, Cons, Pricing, and Who Should Buy
What Is Nvidia Nemotron and Who Is It For?
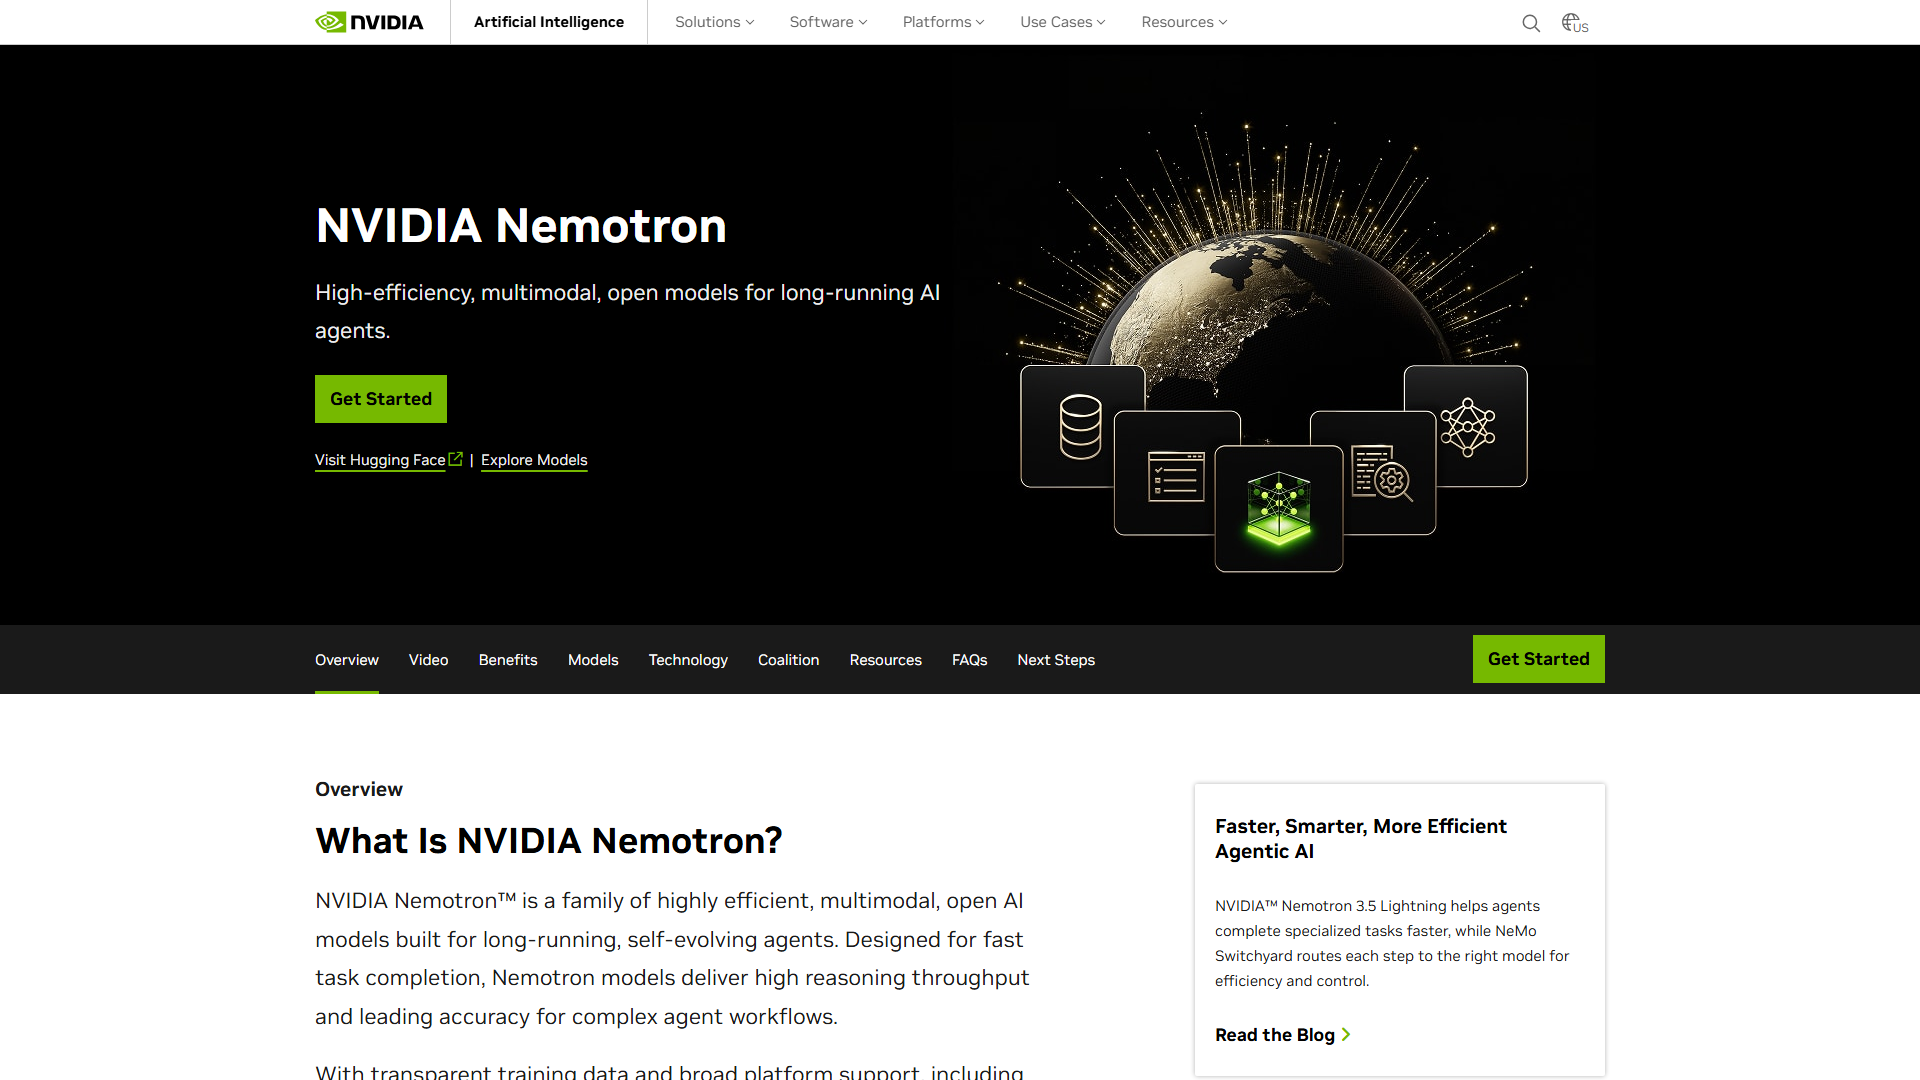
What is Nvidia Nemotron? It is NVIDIA’s family of open foundation models built for reasoning, tool calling, and production LLM serving—not a single chat app.
Nvidia Nemotron Lightning refers to the newer Lightning-oriented Nemotron path highlighted with NeMo Switchyard for mixed workloads on RTX and DGX systems, as described in the NVIDIA Nemotron Lightning and Switchyard announcement.
Primary buyers are AI engineers evaluating open NVIDIA foundation models and ML teams shipping agentic workflows with measurable TCO.
From a business perspective, Nemotron competes with Meta Llama and Google Gemma as a self-hostable model layer, while NVIDIA’s stack adds routing and hardware-aligned serving options.
What is Nvidia Nemotron Lightning?
Nemotron Lightning is best read as a productization path: faster agent loops, model-size choice, and Switchyard routing instead of one static endpoint.
Teams use it when Pareto trade-offs between speed and accuracy matter more than a closed, single-vendor chat SKU.
Who should buy (and who should not)
Buy if you already run NVIDIA GPUs, need open weights for customization, and can own serving, evals, and safety gates.
Skip—or delay—if you need a fully managed SaaS LLM with published per-seat invoices and zero infra ownership.
Nvidia Nemotron’s Standout Features (And Hidden Limitations)
What are Nvidia Nemotron features in practice? Open model variants, agent-oriented serving, and Switchyard routing sit at the center of the value case.
According to the official NVIDIA Nemotron foundation models page, the lineup is positioned as open NVIDIA foundation models for builders—not a closed consumer chatbot.
Looking at market positioning, the commercial edge is stack control: customize prompts, tools, and fine-tunes without surrendering the full model layer to a black-box vendor.
Why Nemotron Lightning fits long-running AI agents
Long-running agents amplify latency tax, tool-call fan-out, and session cost; Lightning’s pitch is sustained throughput without abandoning accuracy targets.
Production agent stacks still need traces, replay, and failure budgets—see how agent-session observability breaks in managed runtimes when comparing hosting and monitoring designs.
Route work with NeMo Switchyard
NeMo Switchyard is the routing layer that sends easy calls to smaller Nemotron variants and harder tasks to larger ones.
Compared to published enterprise averages for single-model over-provisioning, router-first designs usually cut idle GPU waste—though NVIDIA’s blog frames the benefit as system design, not a guaranteed savings formula; see the Lightning and Switchyard technical overview.
Customize Nemotron out of the box
How to use Nvidia Nemotron in a customization workflow: start from open weights, add domain adapters, then bind tools with a strict schema.
How to use Nvidia Nemotron 3 family variants follows the same pattern—pick Nano/Super/Ultra-class sizes for cost vs quality, then freeze eval gates before production traffic.
Accuracy–speed Pareto and the real limits
On the accuracy–speed frontier, Lightning’s business claim is better operating points for agents, not magic accuracy above every closed frontier model.
Hidden limits remain: you still own quantization choices, guardrails, and regression testing when weights or routers change.
The Real Cost: Nvidia Nemotron Pricing Breakdown
How much does Nvidia Nemotron API pricing cost? There is no single public SaaS menu that lists a fixed “Nemotron Lightning” monthly plan price in the materials reviewed for this brief.
No public pricing / contact sales required for many enterprise DGX Cloud and volume serving arrangements—confirm live quotes before budgeting.
Nvidia Nemotron API pricing, when offered through NVIDIA’s API catalogs or cloud partners, is typically usage-metered; treat any remembered dollar rates as stale unless verified on the vendor page.
When we factor in TCO, self-hosting open weights shifts spend from per-token invoices to GPUs, power, SRE time, and evaluation pipelines.
Cost model comparison (TCO lens)
Self-host CapEx/OpEx favors teams with existing NVIDIA fleets and predictable agent traffic.
API or cloud endpoints favor teams that value elasticity and can accept meter variance—re-check the NVIDIA Nemotron product page and linked API catalogs before finance sign-off.
Does Nvidia Nemotron offer a free API?
Trial or promotional API access may appear in NVIDIA developer catalogs from time to time, but “free forever production API” should not be assumed for budget models.
Is Nvidia Nemotron open source? Many Nemotron model releases ship as open weights under NVIDIA’s open-model terms—weights openness is not the same as free unlimited hosted inference.
Where Nvidia Nemotron Falls Short (Critical Analysis)
Is Nvidia Nemotron 3 Super good? For open-model agent stacks it is a serious contender, but it is not an automatic win against every Meta Llama or Google Gemma deployment without your own benchmarks.
The sharpest commercial gap is price transparency: finance teams that need a published $ / month SaaS card will find Nemotron harder to socialize than seat-based tools.
Another gap is ecosystem concentration—routing, GPUs, and tooling skew NVIDIA-centric, which is efficient for NVIDIA shops and costly for multi-cloud model strategies.
Common implementation mistakes
Mistake one: putting every tool call on the largest Super-class model and ignoring Switchyard-style routing.
Mistake two: shipping agents without session observability, then blaming the model when retries inflate spend.
Alternatives to pressure-test
Run a bake-off against Meta Llama and Google Gemma on the same tool schemas, latency SLOs, and safety tests.
Keep the bake-off hardware-normalized; otherwise Pareto charts measure GPUs, not models.
Final Verdict: Is Nvidia Nemotron Worth the Investment?
Nvidia Nemotron Lightning is worth the investment when open weights, agent routing, and NVIDIA hardware already sit on your roadmap.
It is a weaker buy when leadership demands a simple published subscription price and zero model-ops ownership.
For scaling companies, published data shows open-model programs succeed when eval harnesses and cost dashboards ship with the first agent MVP—not after overruns appear.
Bottom line: fund a time-boxed pilot with Nano-to-Super routing, measure $/successful task, then negotiate enterprise serving terms with current quotes—not memorized rates.
Investment takeaway for AI and ML leaders
Nvidia Nemotron Lightning should be scored as infrastructure strategy: model openness plus routing, not a marketing SKU with a single list price.
Confirm nvidia nemotron api pricing and enterprise terms on current NVIDIA and partner pages, then approve spend only after $/successful agent task clears your hurdle rate.
If that unit economy holds against Meta Llama and Google Gemma on identical evals, the investment case is sound; if not, keep Nemotron as a secondary router target rather than the default.